 cast_otter
AI API prices, October 2026: same chatbot, a 100x gap
We checked per-million-token prices for Claude, Gemini, OpenAI, Grok and Workers AI on the official pages on 2026-10-11. For a 2,000-request-a-day chatbot, the monthly bill runs from $13.95 to $1,395.
$13.95 and $1,395.
That's the monthly API bill for the same customer-support chatbot. The only thing that changed was the model, and the gap is 100x.
Between late September and early October, new models shipped from Claude, GPT and Grok, and the price sheets moved with them. So we re-checked five providers on their official pricing pages and priced one workload the same way across all of them.
※ Prices checked Oct 11, 2026 (KST). Standard tier, short prompts. Prices change often, so check the official page before you pay.
What's inside
- The price board, per million tokens
- Turning it into a monthly chatbot bill
- Three things the price board doesn't show: caching, long prompts, tokenizers
- New models this month
- How to run your own numbers
1. The price board
Input / cached input / output, in USD per million tokens.
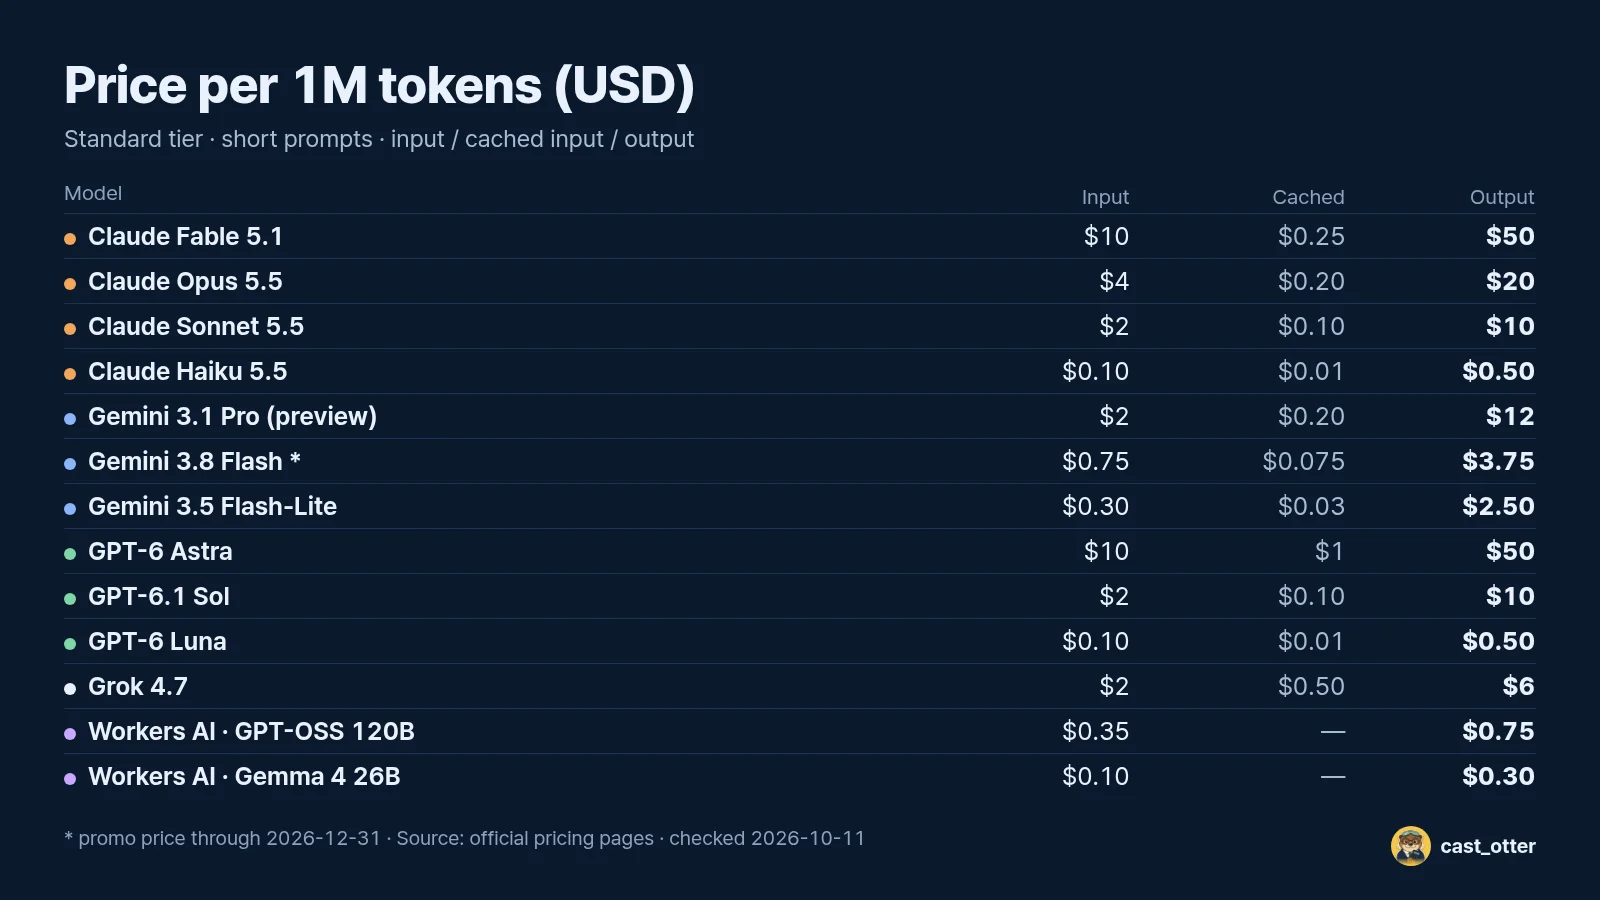
Roughly three tiers:
- Top tier: Claude Fable 5.1 and GPT-6 Astra, at $10 in and $50 out
- Mid tier: Claude Sonnet 5.5, GPT-6.1 Sol, Gemini 3.1 Pro (preview) and Grok 4.7, at $2 in and $6–12 out
- Light tier: Claude Haiku 5.5 and GPT-6 Luna, at $0.10 in and $0.50 out
Gemini 3.8 Flash is on a promo price ($0.75 in, $3.75 out) through Dec 31, 2026. After that it doubles to $1.50 in and $7.50 out.
2. Turning it into a monthly bill
Per-token prices are hard to feel, so we fixed one workload:
- 2,000 requests a day for 30 days
- 1,500 input and 300 output tokens per request
- half the input read from cache (system prompt and other repeated parts)
That comes to 45M regular input tokens, 45M cached input tokens and 18M output tokens a month.
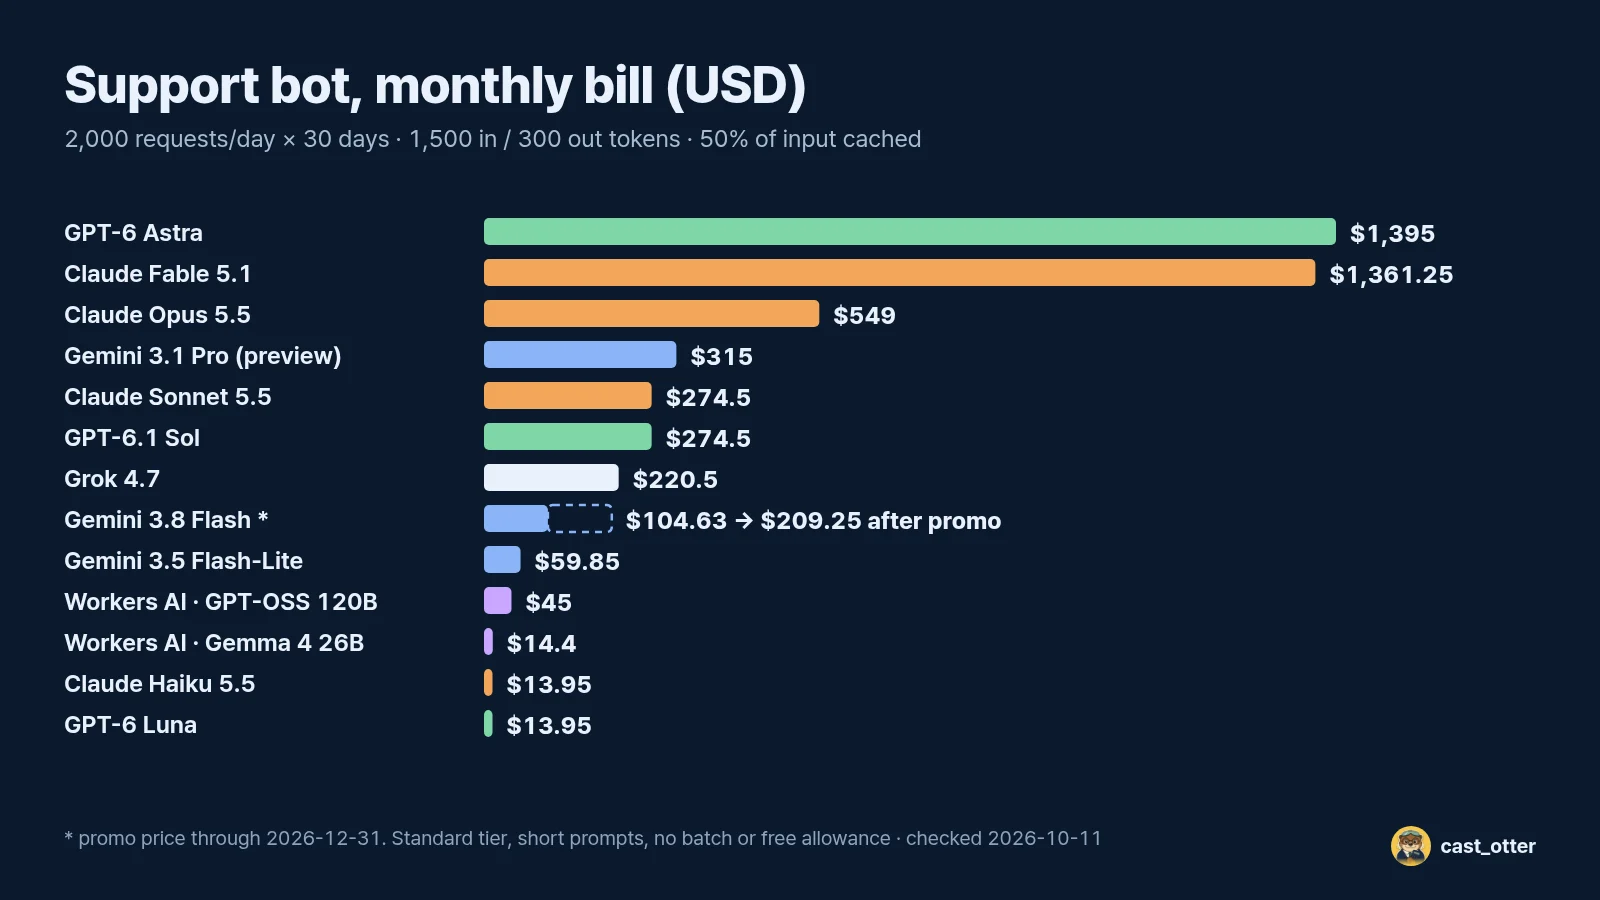
- GPT-6 Astra $1,395; Claude Fable 5.1 $1,361.25
- Claude Opus 5.5 $549
- Gemini 3.1 Pro $315
- Claude Sonnet 5.5 and GPT-6.1 Sol $274.50
- Grok 4.7 $220.50
- Gemini 3.8 Flash $104.63 (about $209 once the promo ends)
- Gemini 3.5 Flash-Lite $59.85
- Workers AI GPT-OSS 120B $45; Gemma 4 26B $14.40
- Claude Haiku 5.5 and GPT-6 Luna $13.95
3. Three things the price board doesn't show
Cache discounts differ. Cached input costs 5% of regular input (a 95% discount) on Claude Sonnet 5.5, Claude Opus 5.5 and GPT-6.1 Sol, and just 2.5% on Claude Fable 5.1. It's 10% (90% off) on Gemini, GPT-6 Astra and Luna, and Claude Haiku 5.5. On Grok 4.7 it's 25% (75% off). The more your prompts repeat, the more this matters.
Long prompts change the rate. Past a certain length, prices step up:
- Claude Haiku 5.5: above 100K tokens, $0.50 in / $2.50 out (5x)
- Gemini 3.1 Pro: above 200K, $4 / $18
- Grok 4.7: above 200K, $4 / $12
- GPT-6 Astra: above 272K, $20 / $75
Tokenizers differ. Anthropic notes that Claude 4.7 and later models count about 30% more tokens for the same text. The same per-token price can still mean a different bill.
4. New models this month
Claude Haiku 5.5 lists 90% below Haiku 4.5 ($1 in, $5 out). Anthropic says it costs "around 75% less to run" on average. The list-price gap and the real bill can be two different numbers.
Grok 4.7 launched at the same price as Grok 4.6.
Gemini 3.8 Flash launched at the same promo price as 3.7 Flash.
One more: on Sept 30 (US time), Google introduced Gemini 4 Argon at an introductory $2 in and $10 out. It's rolling out to cyber defenders first, so we left it out of the comparison.
5. How to run your own numbers
The numbers above come from one workload. Change the request count, token lengths or cache share, and the ranking can move.
- Enter requests per day and input/output tokens per request.
- Set the cache share to the part of your prompt that repeats (system prompt, documents).
- If results can wait, try batch (50% off). Anthropic, Google and OpenAI list it.
- If you send long documents, check whether long-prompt pricing kicks in.
The cast_otter AI API Cost Calculator covers all of these. The example above matches its "Support bot" preset.
Sources
- Anthropic, Claude pricing (checked 2026-10-11): https://docs.claude.com/en/docs/about-claude/pricing
- Google, Gemini API pricing (checked 2026-10-11): https://ai.google.dev/gemini-api/docs/pricing
- OpenAI, API pricing (checked 2026-10-11): https://platform.openai.com/docs/pricing
- xAI, models and pricing (checked 2026-10-11): https://docs.x.ai/docs/models
- Cloudflare, Workers AI pricing (checked 2026-10-11): https://developers.cloudflare.com/workers-ai/platform/pricing/
- Embedded posts are from the providers' official X accounts. Gemini 4 Argon pricing is from a post by Google's Logan Kilpatrick.
- Monthly bills are cast_otter calculations (standard tier, short prompts, no batch, free allowance or tax).
More articles
TSMC Q3: revenue is already out. Margins are not
Add up July–September monthly sales and you get NT$1,494.2B, about 2% above the top of guidance. On Thursday Oct 15 the number to watch is margin, not revenue.
Read
ASML Q3: the bar is already set high
ASML guided Q3 net sales to €11.0–12.0B, 18–29% above Q2. On Wednesday Oct 14, watch margins, the Q4 math and what the company says about orders.
Read